# What Are Constraining Prompts? Setting Limits for LLMs
> Constraining prompts turn context window engineering into a rigid interface contract between LLMs and the software systems that consume their output.
Source: https://camnangai.com/en/engineering/what-are-constraining-prompts
Published: 2026-09-03
**Constraining prompts** are the practice of designing the [context
window](https://camnangai.com/en/knowledge/context-window) — system instructions, schemas, and delimiters — to act as a
rigid interface contract between probabilistic [LLMs](https://camnangai.com/en/knowledge/what-is-an-llm) and
deterministic software systems.
Once you apply those constraints, the prompt stops being a natural language request and becomes a
component of the application's architecture, held to the same expectations as any other component.
You move from prompt engineering to [context engineering](https://camnangai.com/en/for/developers/context-engineering),
where the objective is to eliminate the model's need to guess the boundaries between instructions
and data.
That shift is what lets you put real gates around security, safety, and operational limits, before,
during, and after the model ingests anything.
## What is a constraining prompt?
The field has been drifting from prompt engineering toward context engineering, where the job is to
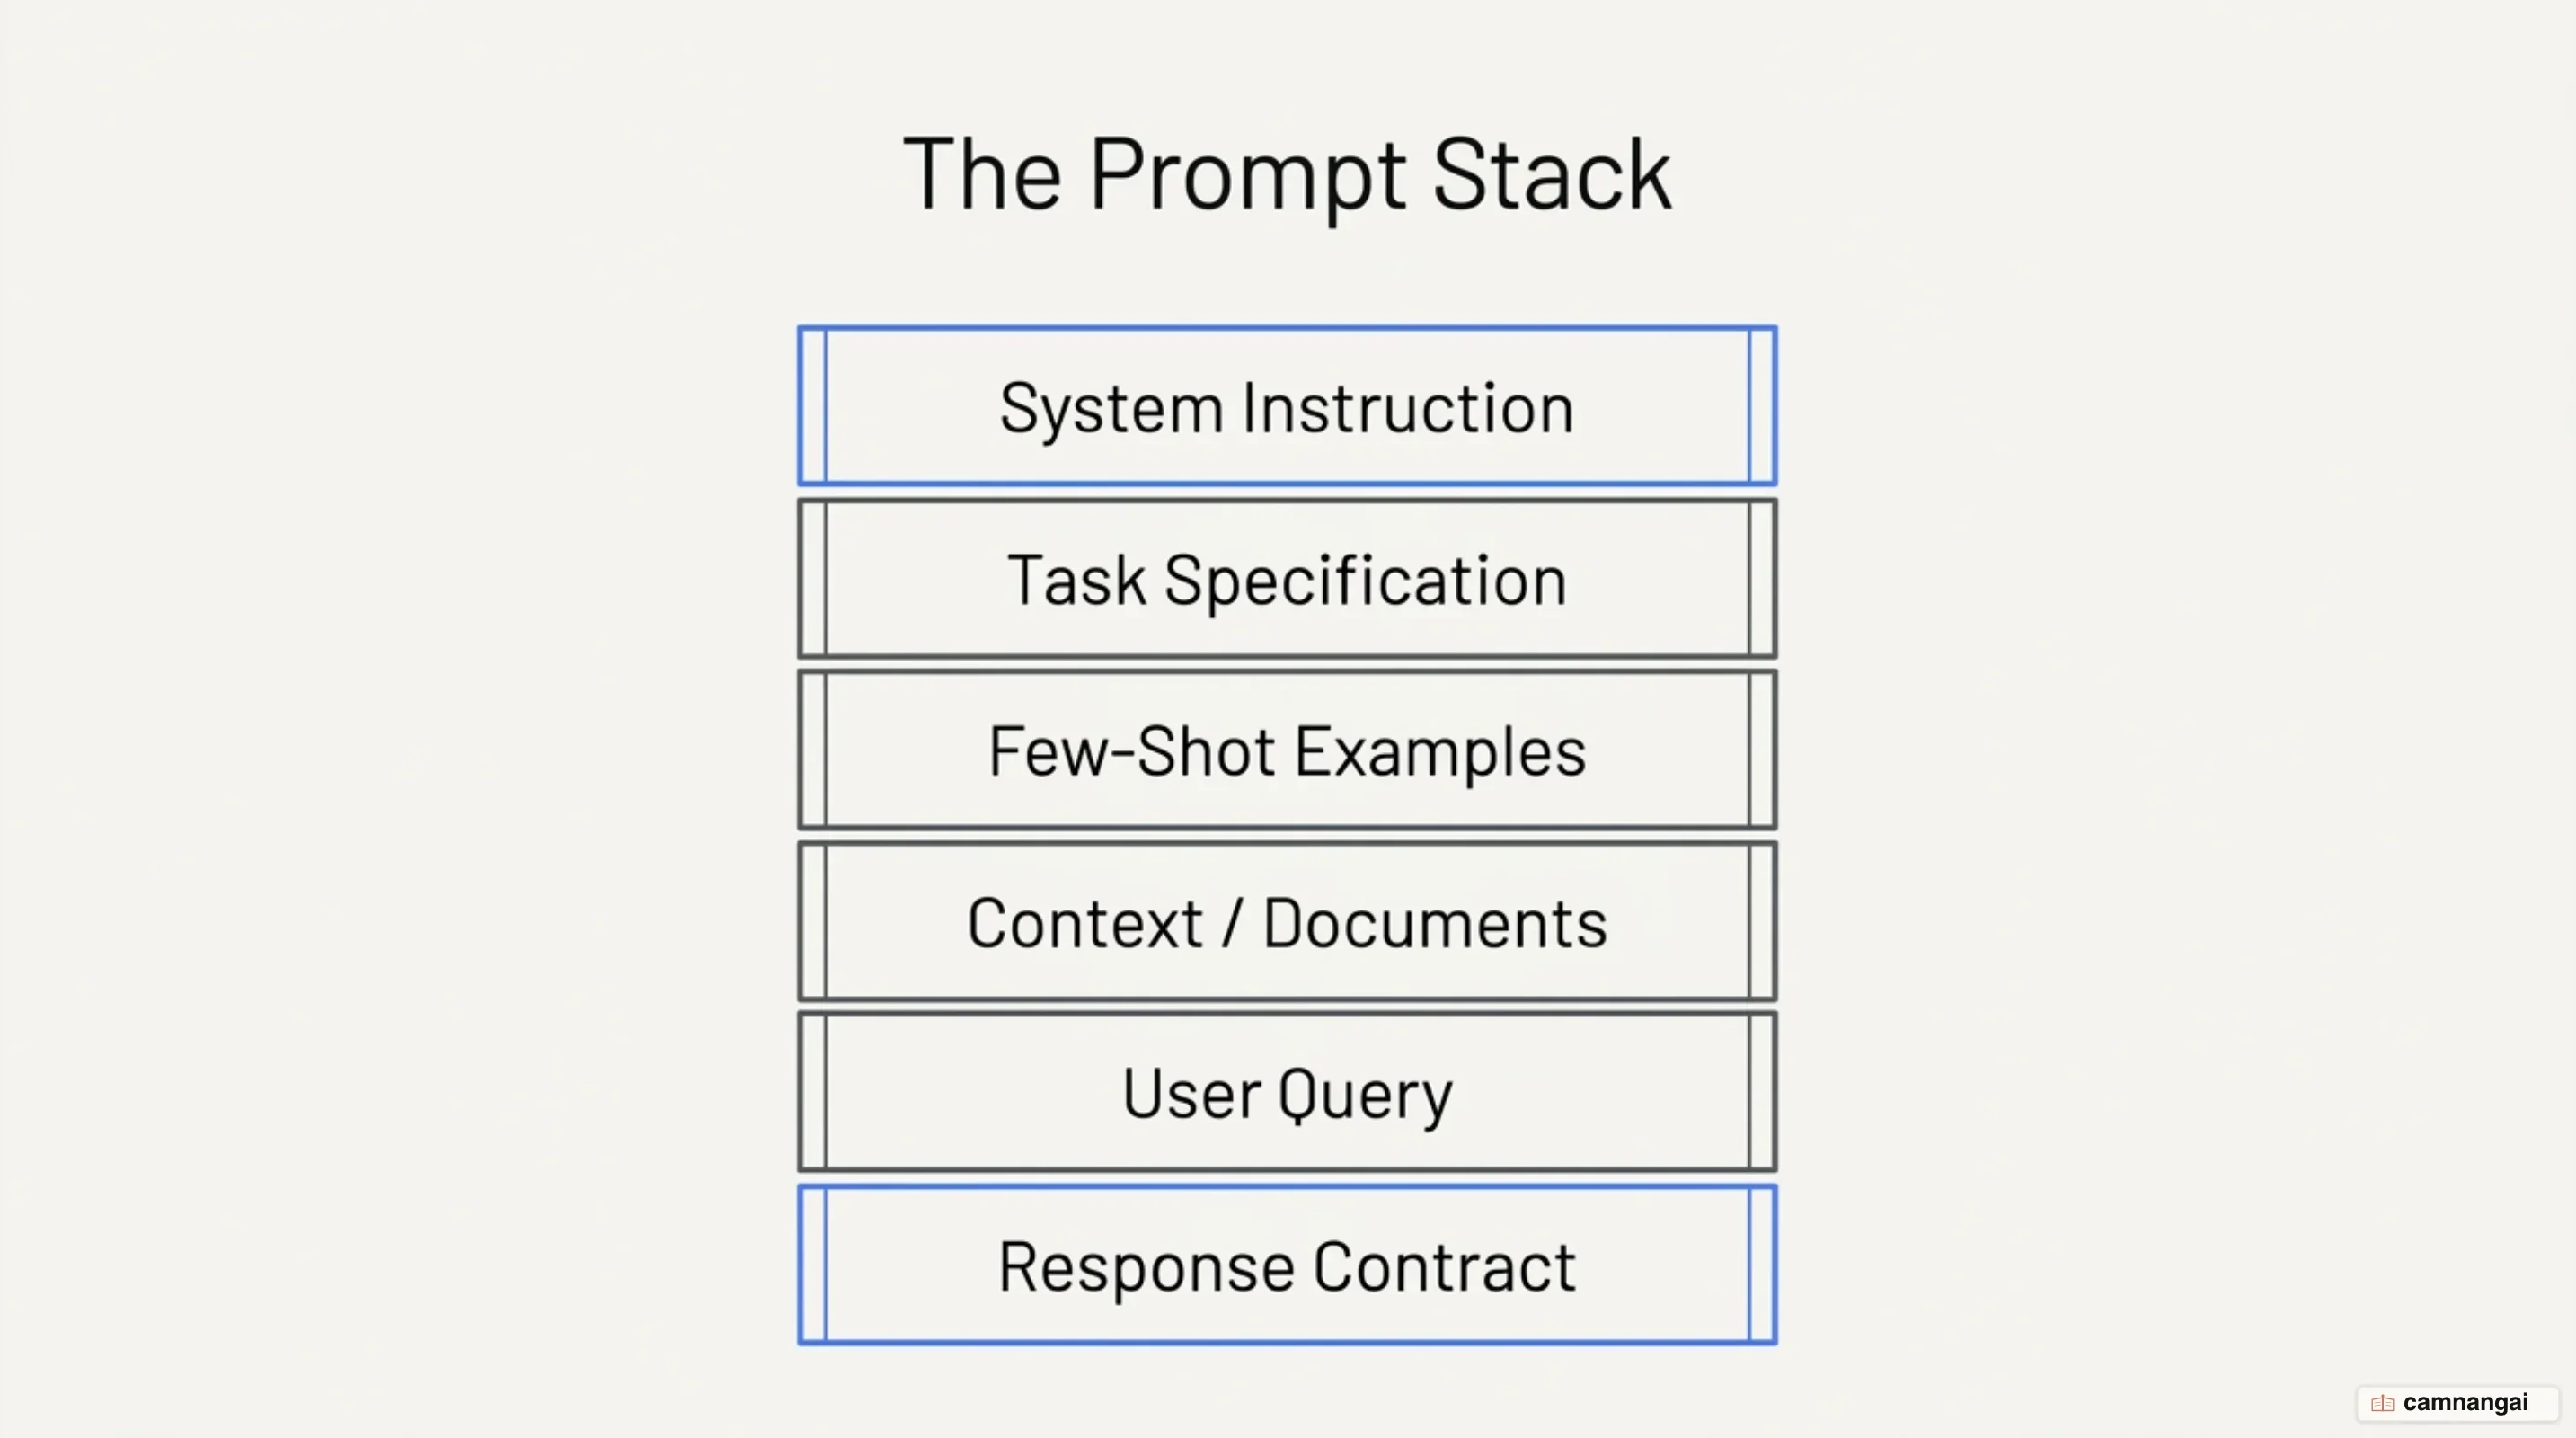
design the whole context window as a stable interface. A **constraining prompt** is a "prompt stack":
stable prefixes (system instructions and tool definitions) sitting above dynamic suffixes (the user's
query and whatever context you retrieved). The model then works inside a sandbox you defined, instead
of leaning on its training data to guess what the objective was.
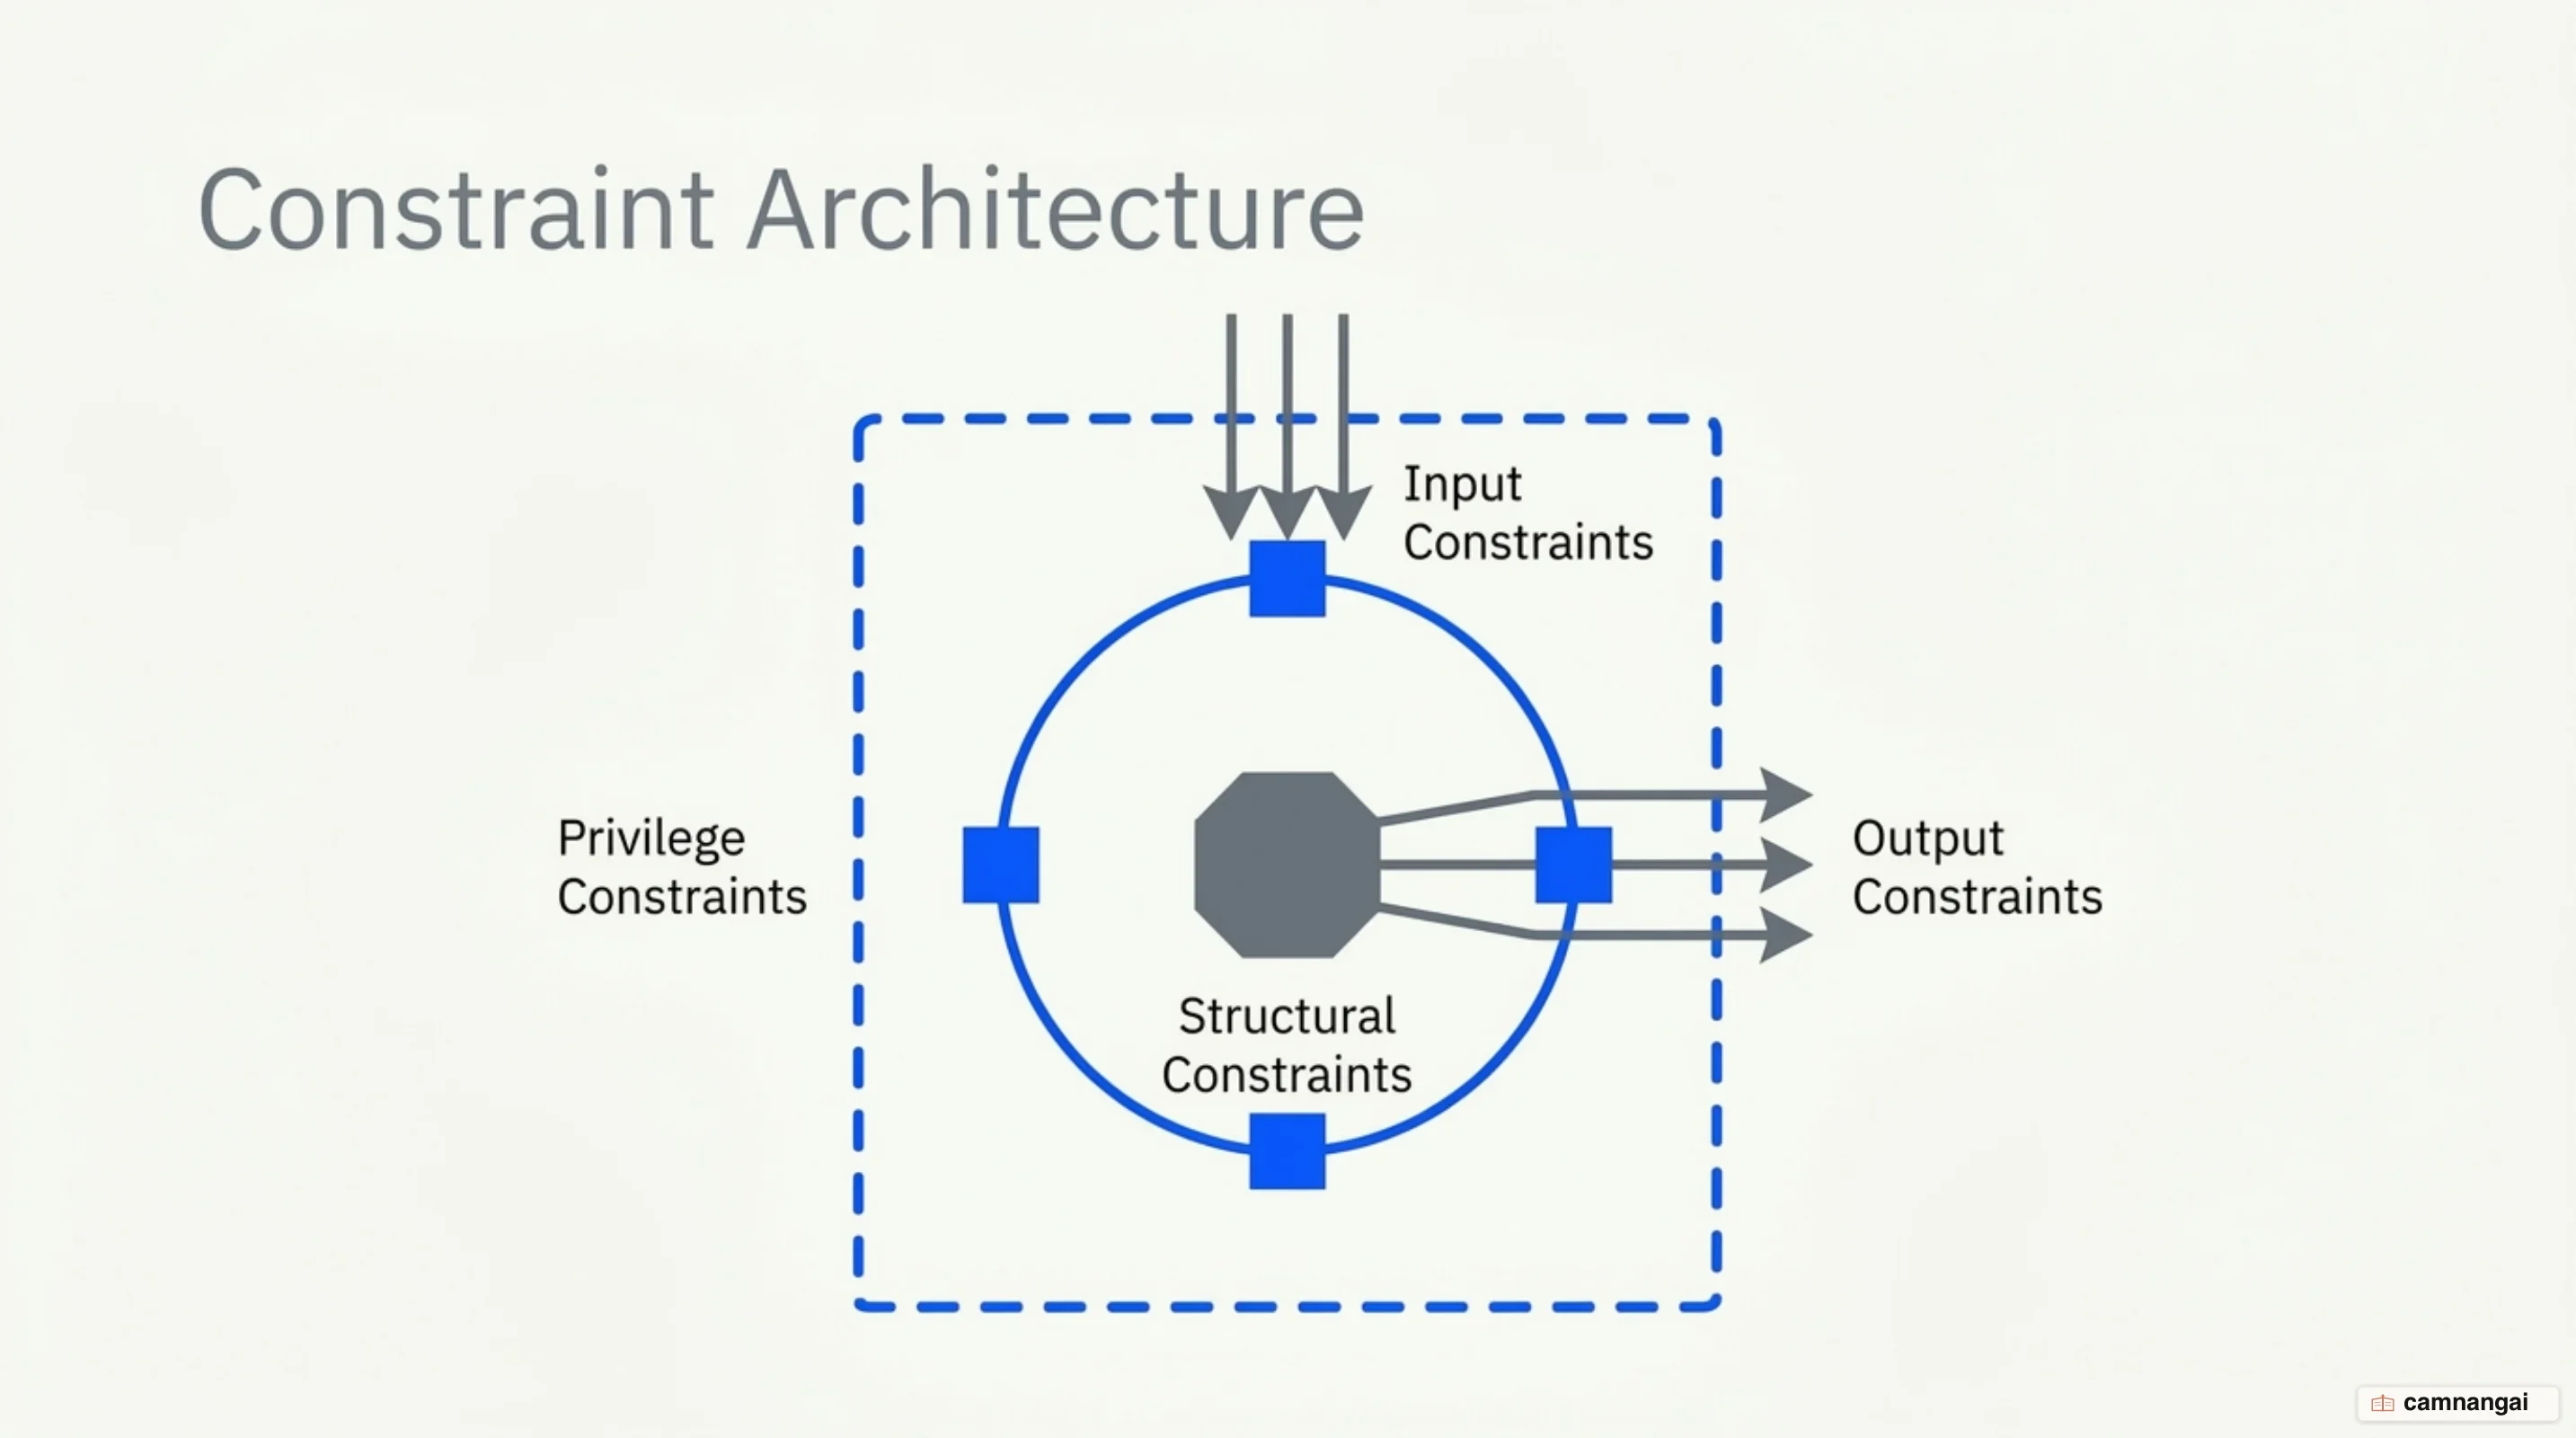
The constraints are gates in the application's lifecycle, and they sit at three stages: before
ingestion, where you validate user input; during processing, where you steer the model's reasoning
path; and after generation, where you filter or reformat the output. Put all three in and the LLM
starts behaving like a module you can reason about, because the non-determinism of generative AI is
boxed in by boundaries you wrote down rather than boundaries you hoped for.
The mental model I keep coming back to is the interface contract. An interface in ordinary systems
engineering says exactly which inputs it accepts and which outputs it guarantees, and a constraining
prompt copies that with explicit boundaries — XML tags or Markdown headers — between instructions
and data. That one separation buys two things: less format fragility, and a model that no longer
confuses the developer's high-authority commands with the user's potentially adversarial data.
## The four kinds of constraint in a system prompt
What separates the four kinds is where they sit in the stack and what they do there. **Role and
scope** comes first, anchoring the model's tone, domain assumptions, and operational limits. Tell it
that it is a compliance analyst or a senior backend engineer and it reaches for that domain's
knowledge ahead of its general-purpose persona, which narrows the distribution of answers you can
get back.
**Task specification** is the layer underneath, covering the objective, the decision rules, and the
failure behavior: how to handle edge cases, and when to refuse a request outright. The part people
skip is uncertainty behavior, which forces the model to say "I don't know" rather than hallucinate
an answer when the evidence is missing from the context you provided.
**Context boundaries** and **response contracts** close the stack. Boundaries use explicit
delimiters to stop the model blurring instructions with provided data, while response contracts pin
the output format down to a specific JSON schema or a fixed set of allowed labels, so a downstream
deterministic system can consume the result without a defensive parse. Identity binding usually
lands at this level too, keeping the model's access to tools and data inside the caller's own roles
and permissions.
```xml
You are a technical support agent. Use ONLY the provided context to answer.
If the answer is not in the context, say "Answer not found."
[Insert technical documentation here]
Return a JSON object with "summary" and "steps" as keys.
```
## Why "don't do X" works worse than "do Y"
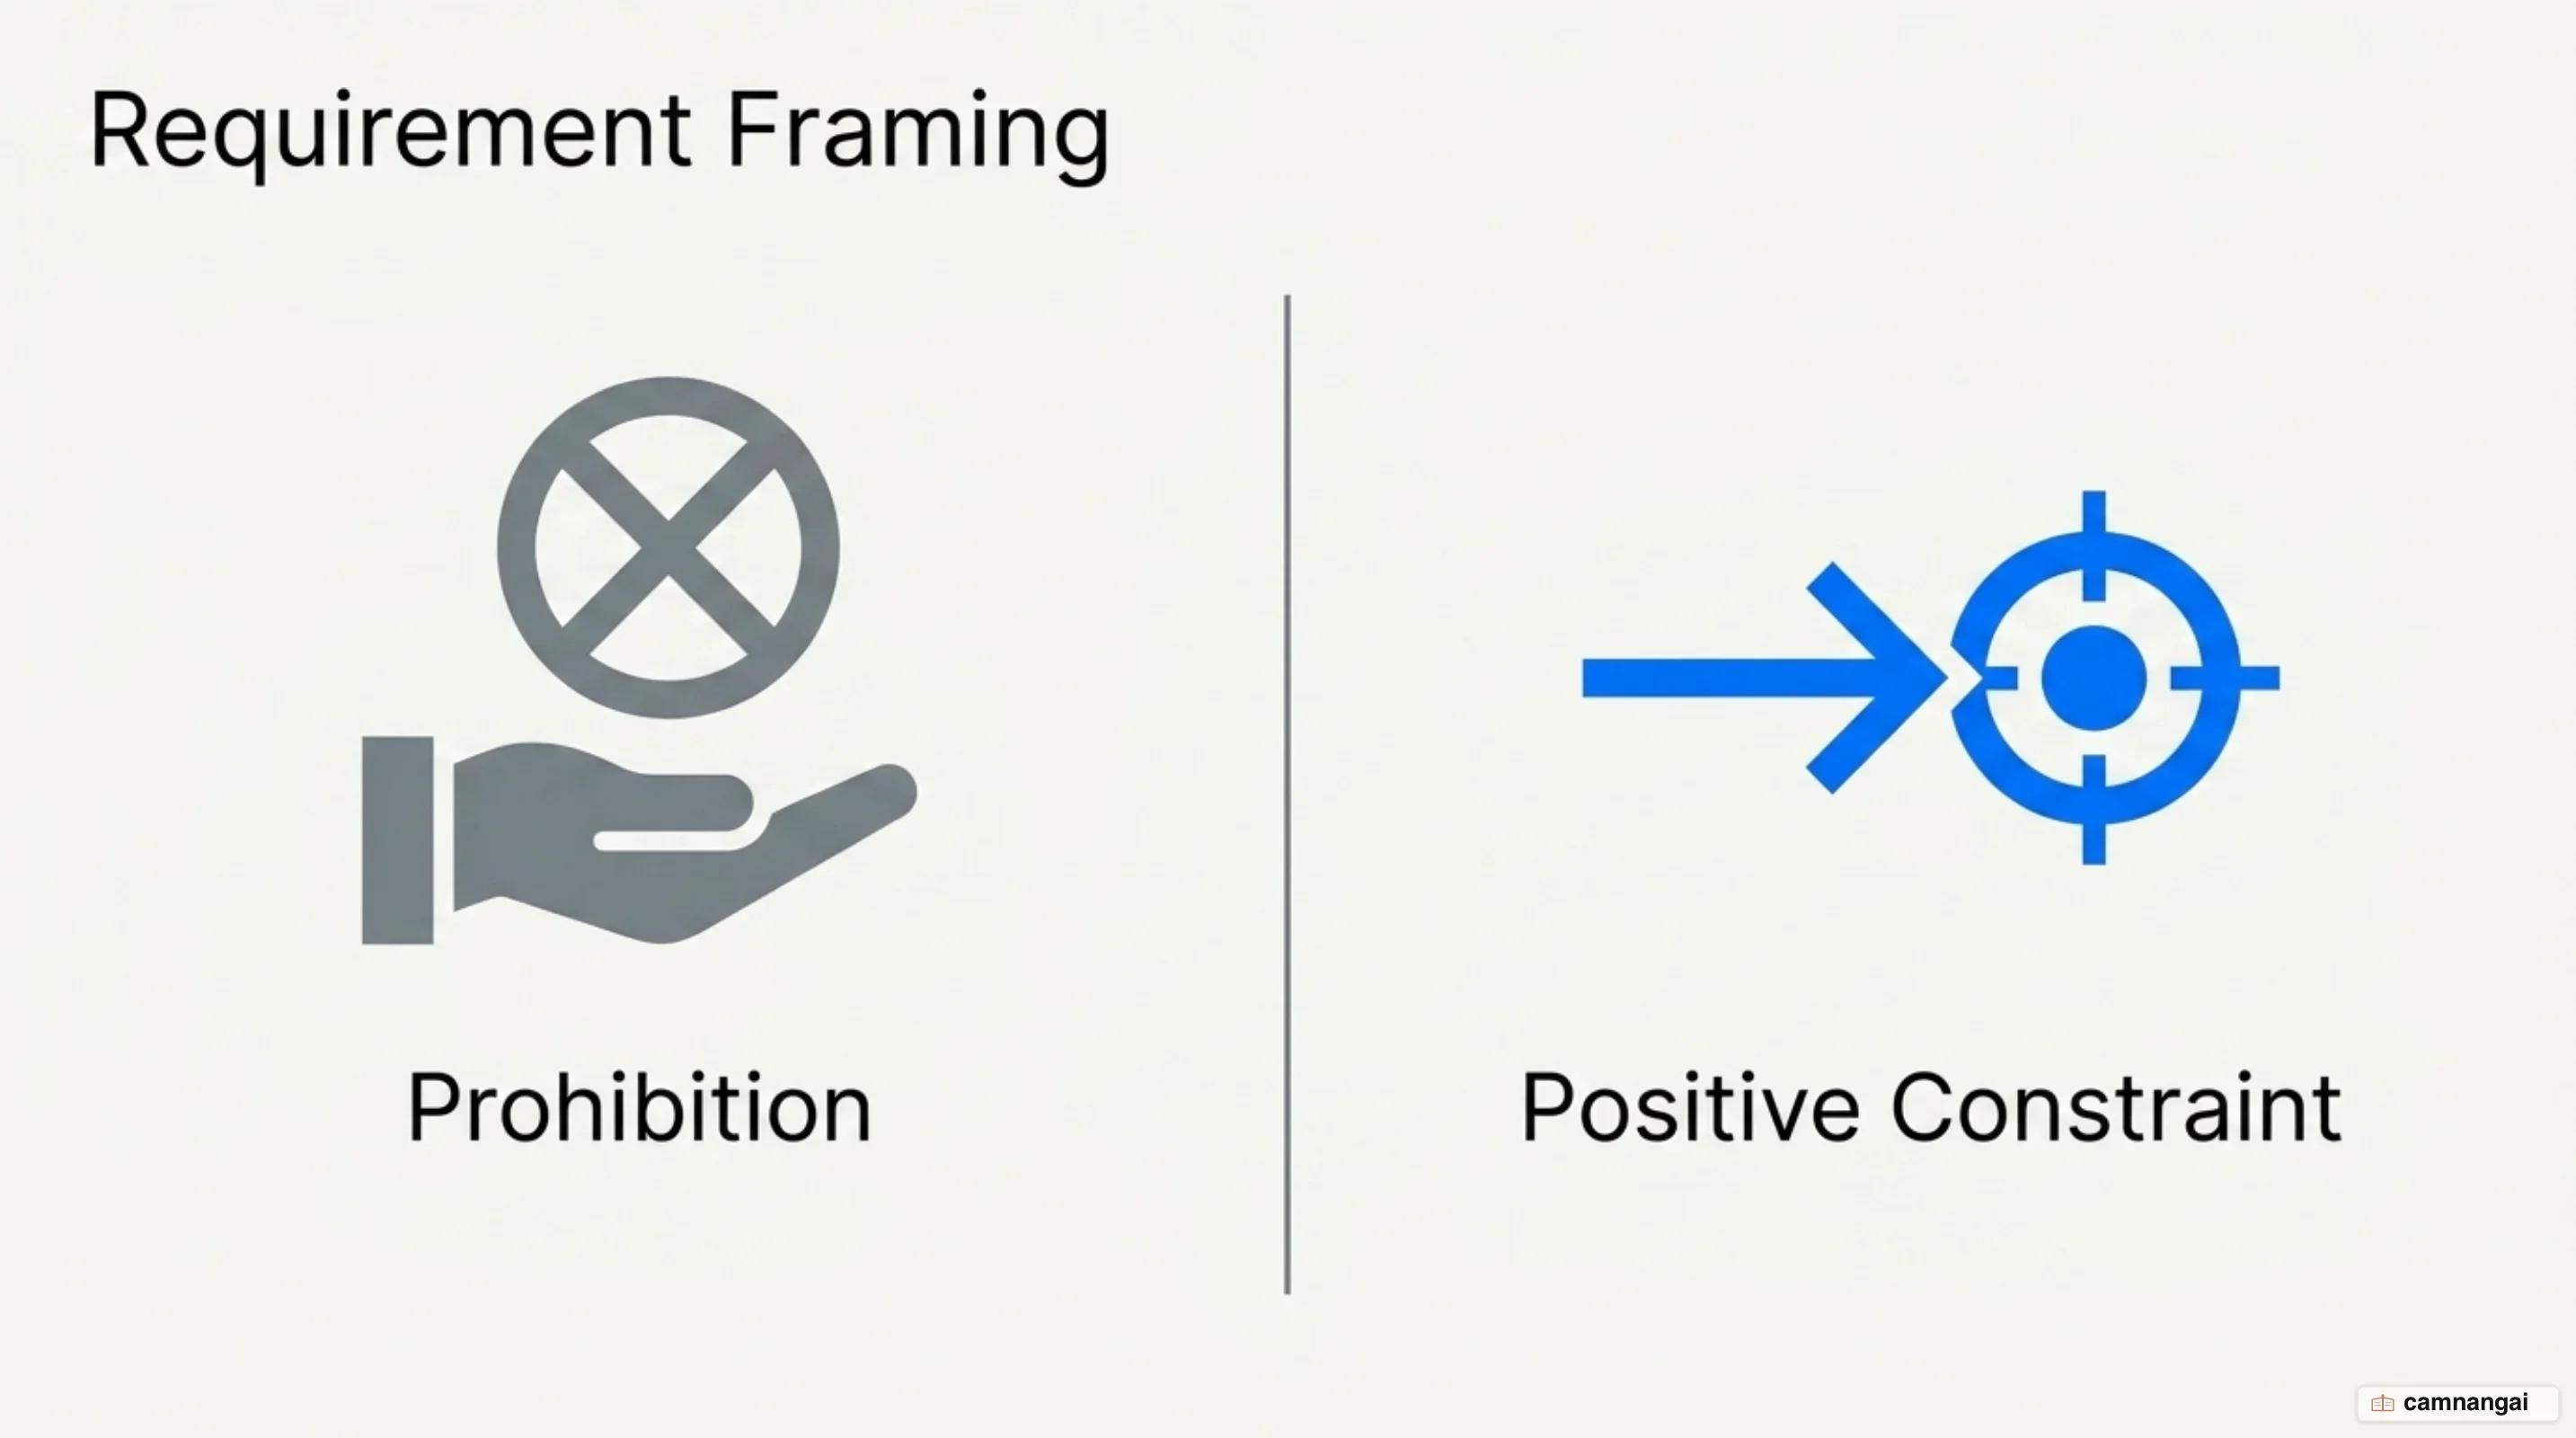
Constraints work better when they describe the behavior you want than when they forbid the one you
don't. An LLM is trained on token prediction, so telling it what not to do drops exactly the tokens
you were trying to avoid into the local context, where they can inadvertently trigger the prohibited
behavior. A positive constraint gives the model one clear path for the next token instead of a
decision tree with a blacklist hanging off it.
Negative instructions are a documented anti-pattern across every frontier model family. Negative
examples in few-shot prompting are frequently less effective than clear, positive patterns, because
they increase the load on the model, which has to keep checking its output against a list of
forbidden states. A positive instruction narrows the focus to a single valid behavior and the
generation gets simpler.
Refusal behavior is where that shift becomes code. Instead of instructing a model
"don't hallucinate", the prompt provides a positive requirement: "If the information is missing from
the provided documents, state 'I do not have enough information to answer.'" This gives the model a
valid, pre-defined exit path that still satisfies the prompt, and what you get back is a failure you
can predict and a deterministic handler can parse. A boring failure mode is the whole point.
```text
Constraint: Your response must be composed entirely of three prose
paragraphs. Use standard paragraph breaks for organization.
```
## Locking the model to the sources you provide
For factual reliability in [retrieval-augmented generation (RAG)](https://camnangai.com/en/knowledge/what-is-rag)
systems, the cheapest thing you can do is quote-grounding: the model has to extract verbatim quotes
from the provided text before it is allowed to synthesize an answer. Making it surface the evidence
first gives you an audit trail you can check by hand, and it cuts the odds of the model injecting
its own training data into the response.
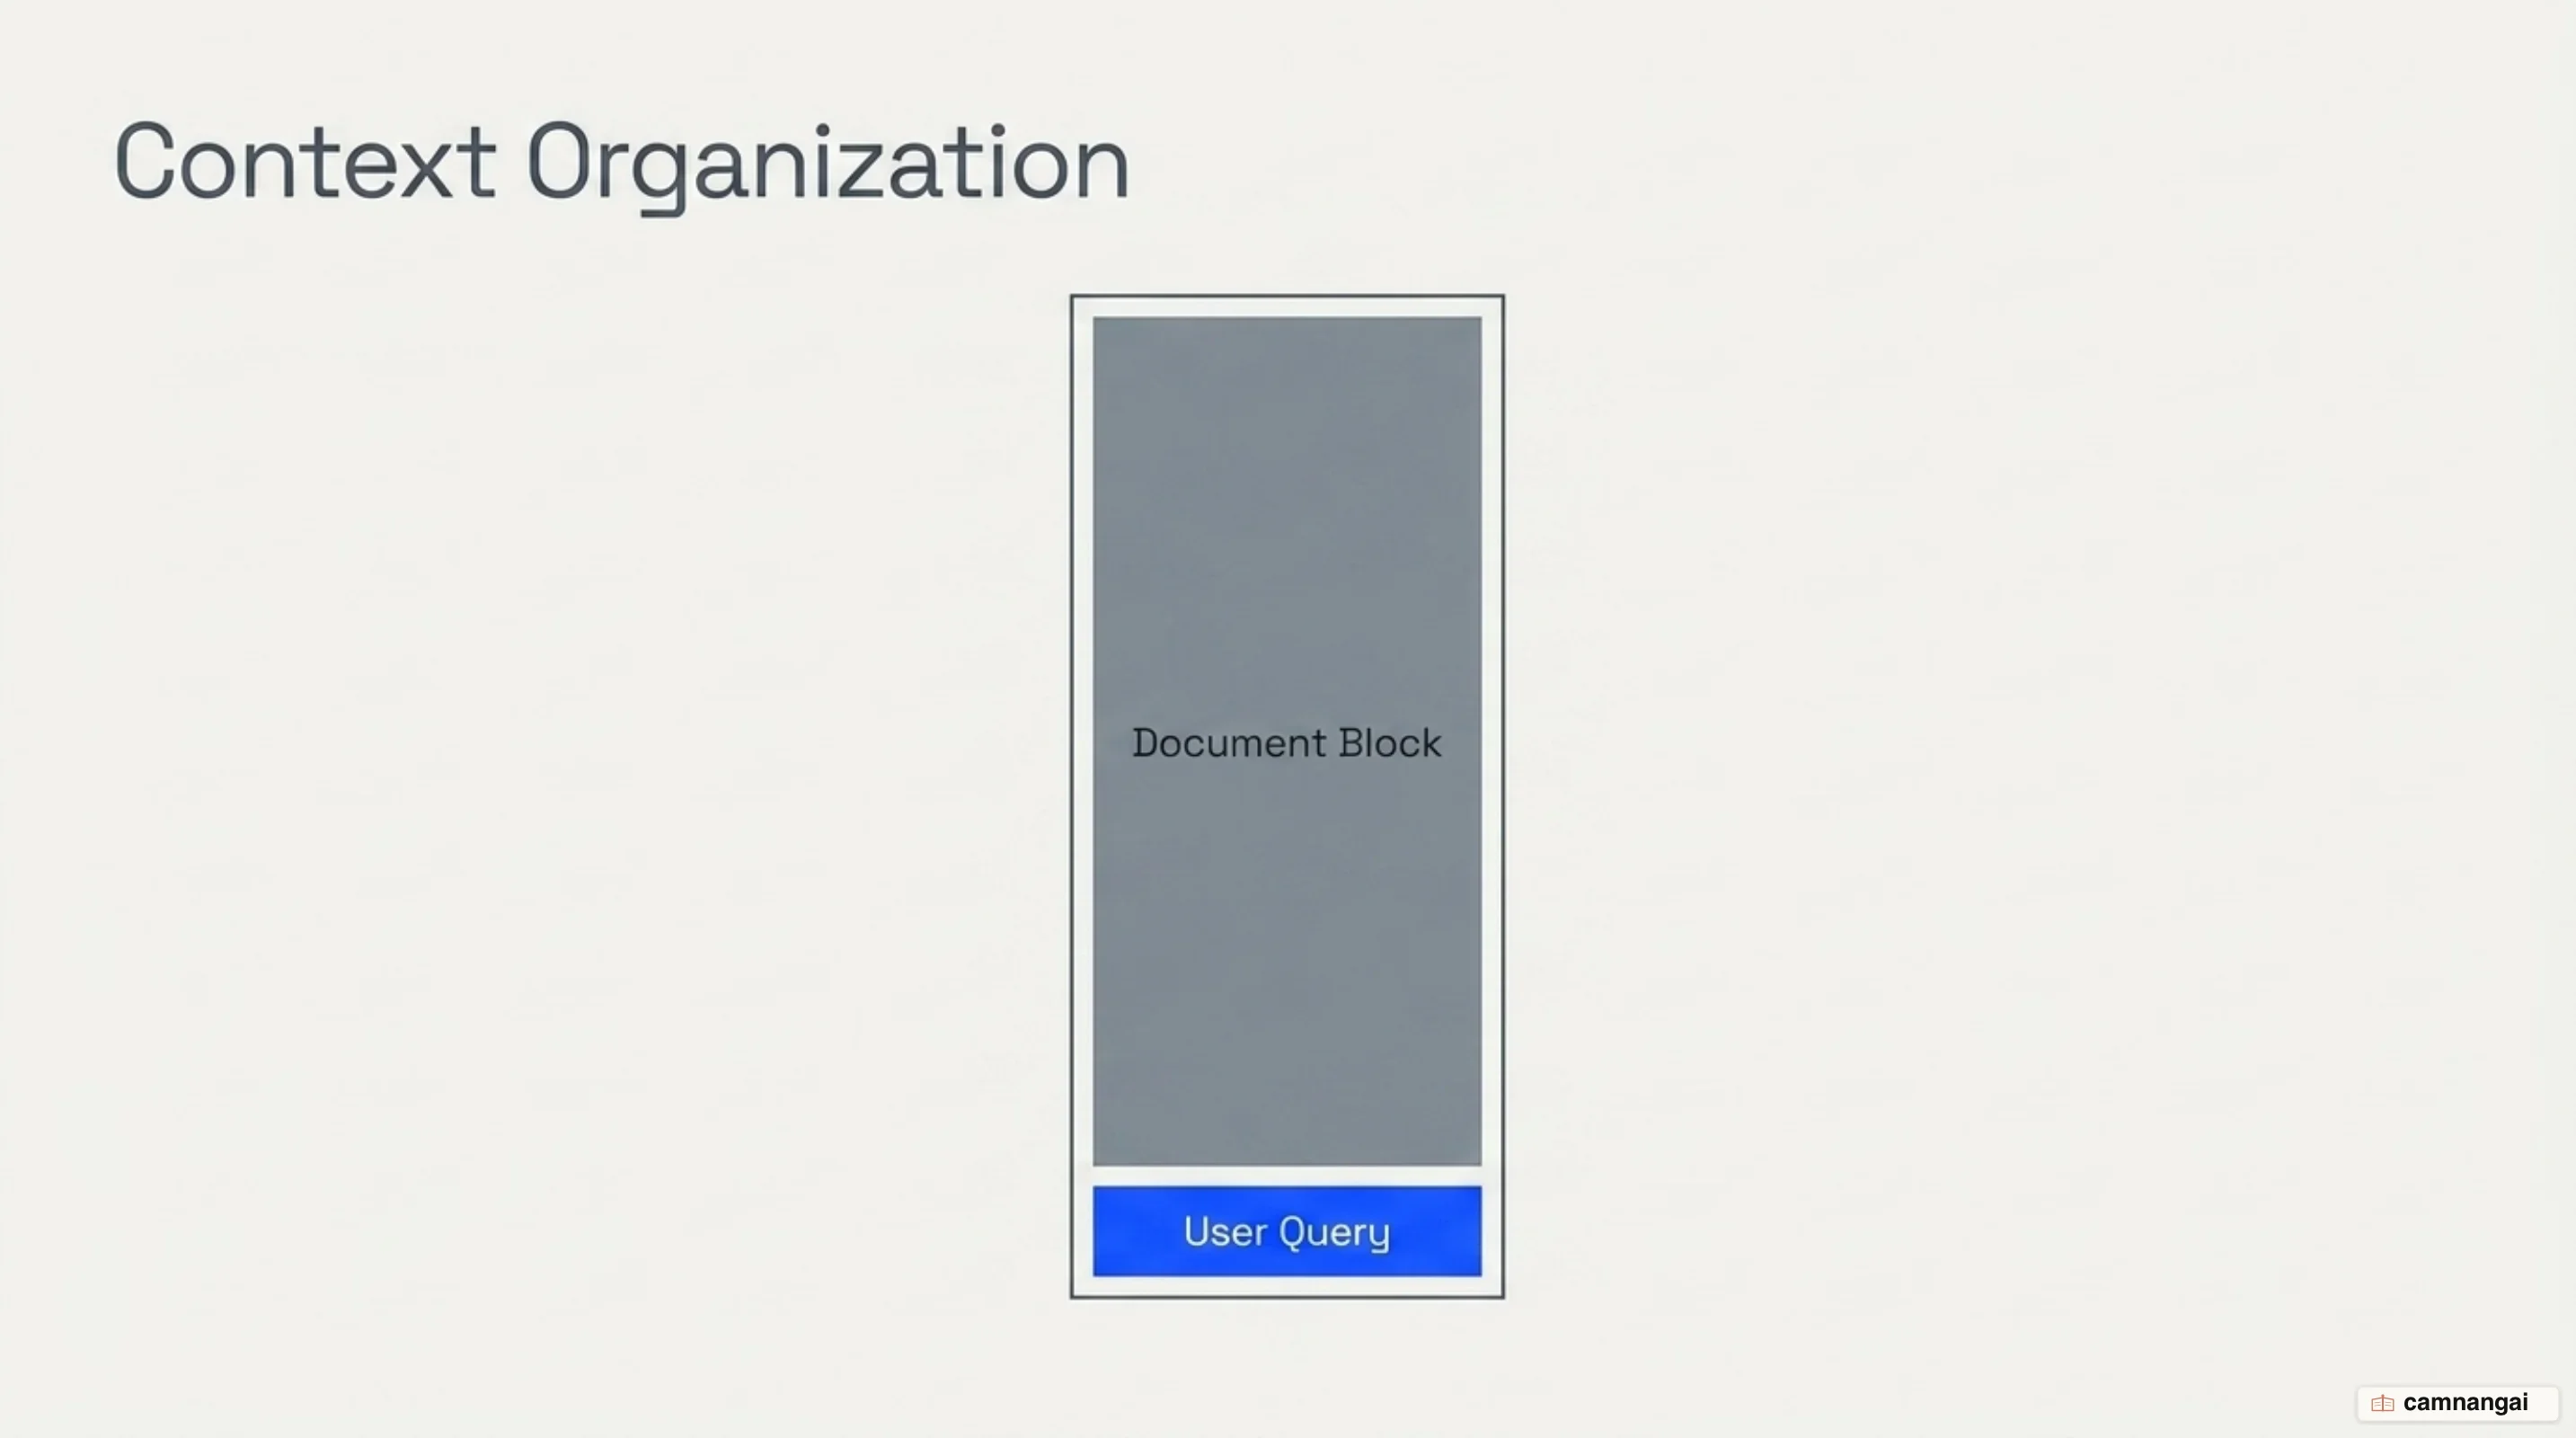
Multi-document context needs explicit XML delimiters, or the documents blur into each other. Tagging
each one with a unique identifier such as `` lets the model tell
conflicting or version-specific information apart instead of averaging across sources, and in a
complex retrieval setup that is the difference between an answer and a plausible-sounding mash-up.
Placement is a real lever in long-context windows. Put long documents and data near the top of the
prompt, above your query and instructions: with inputs of 20k tokens or more, queries at the end
improve response quality by up to 30 percent in tests, most visibly on complex multi-document
inputs. Bookending, which means repeating the critical behavioral instructions at both the beginning
and the end of the stack, keeps the model focused despite the volume of data in between. And an
external knowledge restriction instruction tells it to disregard its internal training set in favor
of the context you hydrated into the current prompt.
## Output format: asking in the prompt versus enforcing at decode time
Asking and enforcing are separated by one thing: which tokens the model is even allowed to emit.
Prompt-based formatting relies on the model following your instructions well enough to produce clean
Markdown or XML. API-level enforcement — OpenAI's Structured Outputs, or Gemini's JSON Schema mode —
works at decode time instead, and it guarantees schema compliance by zeroing out the probability of
every non-compliant token.
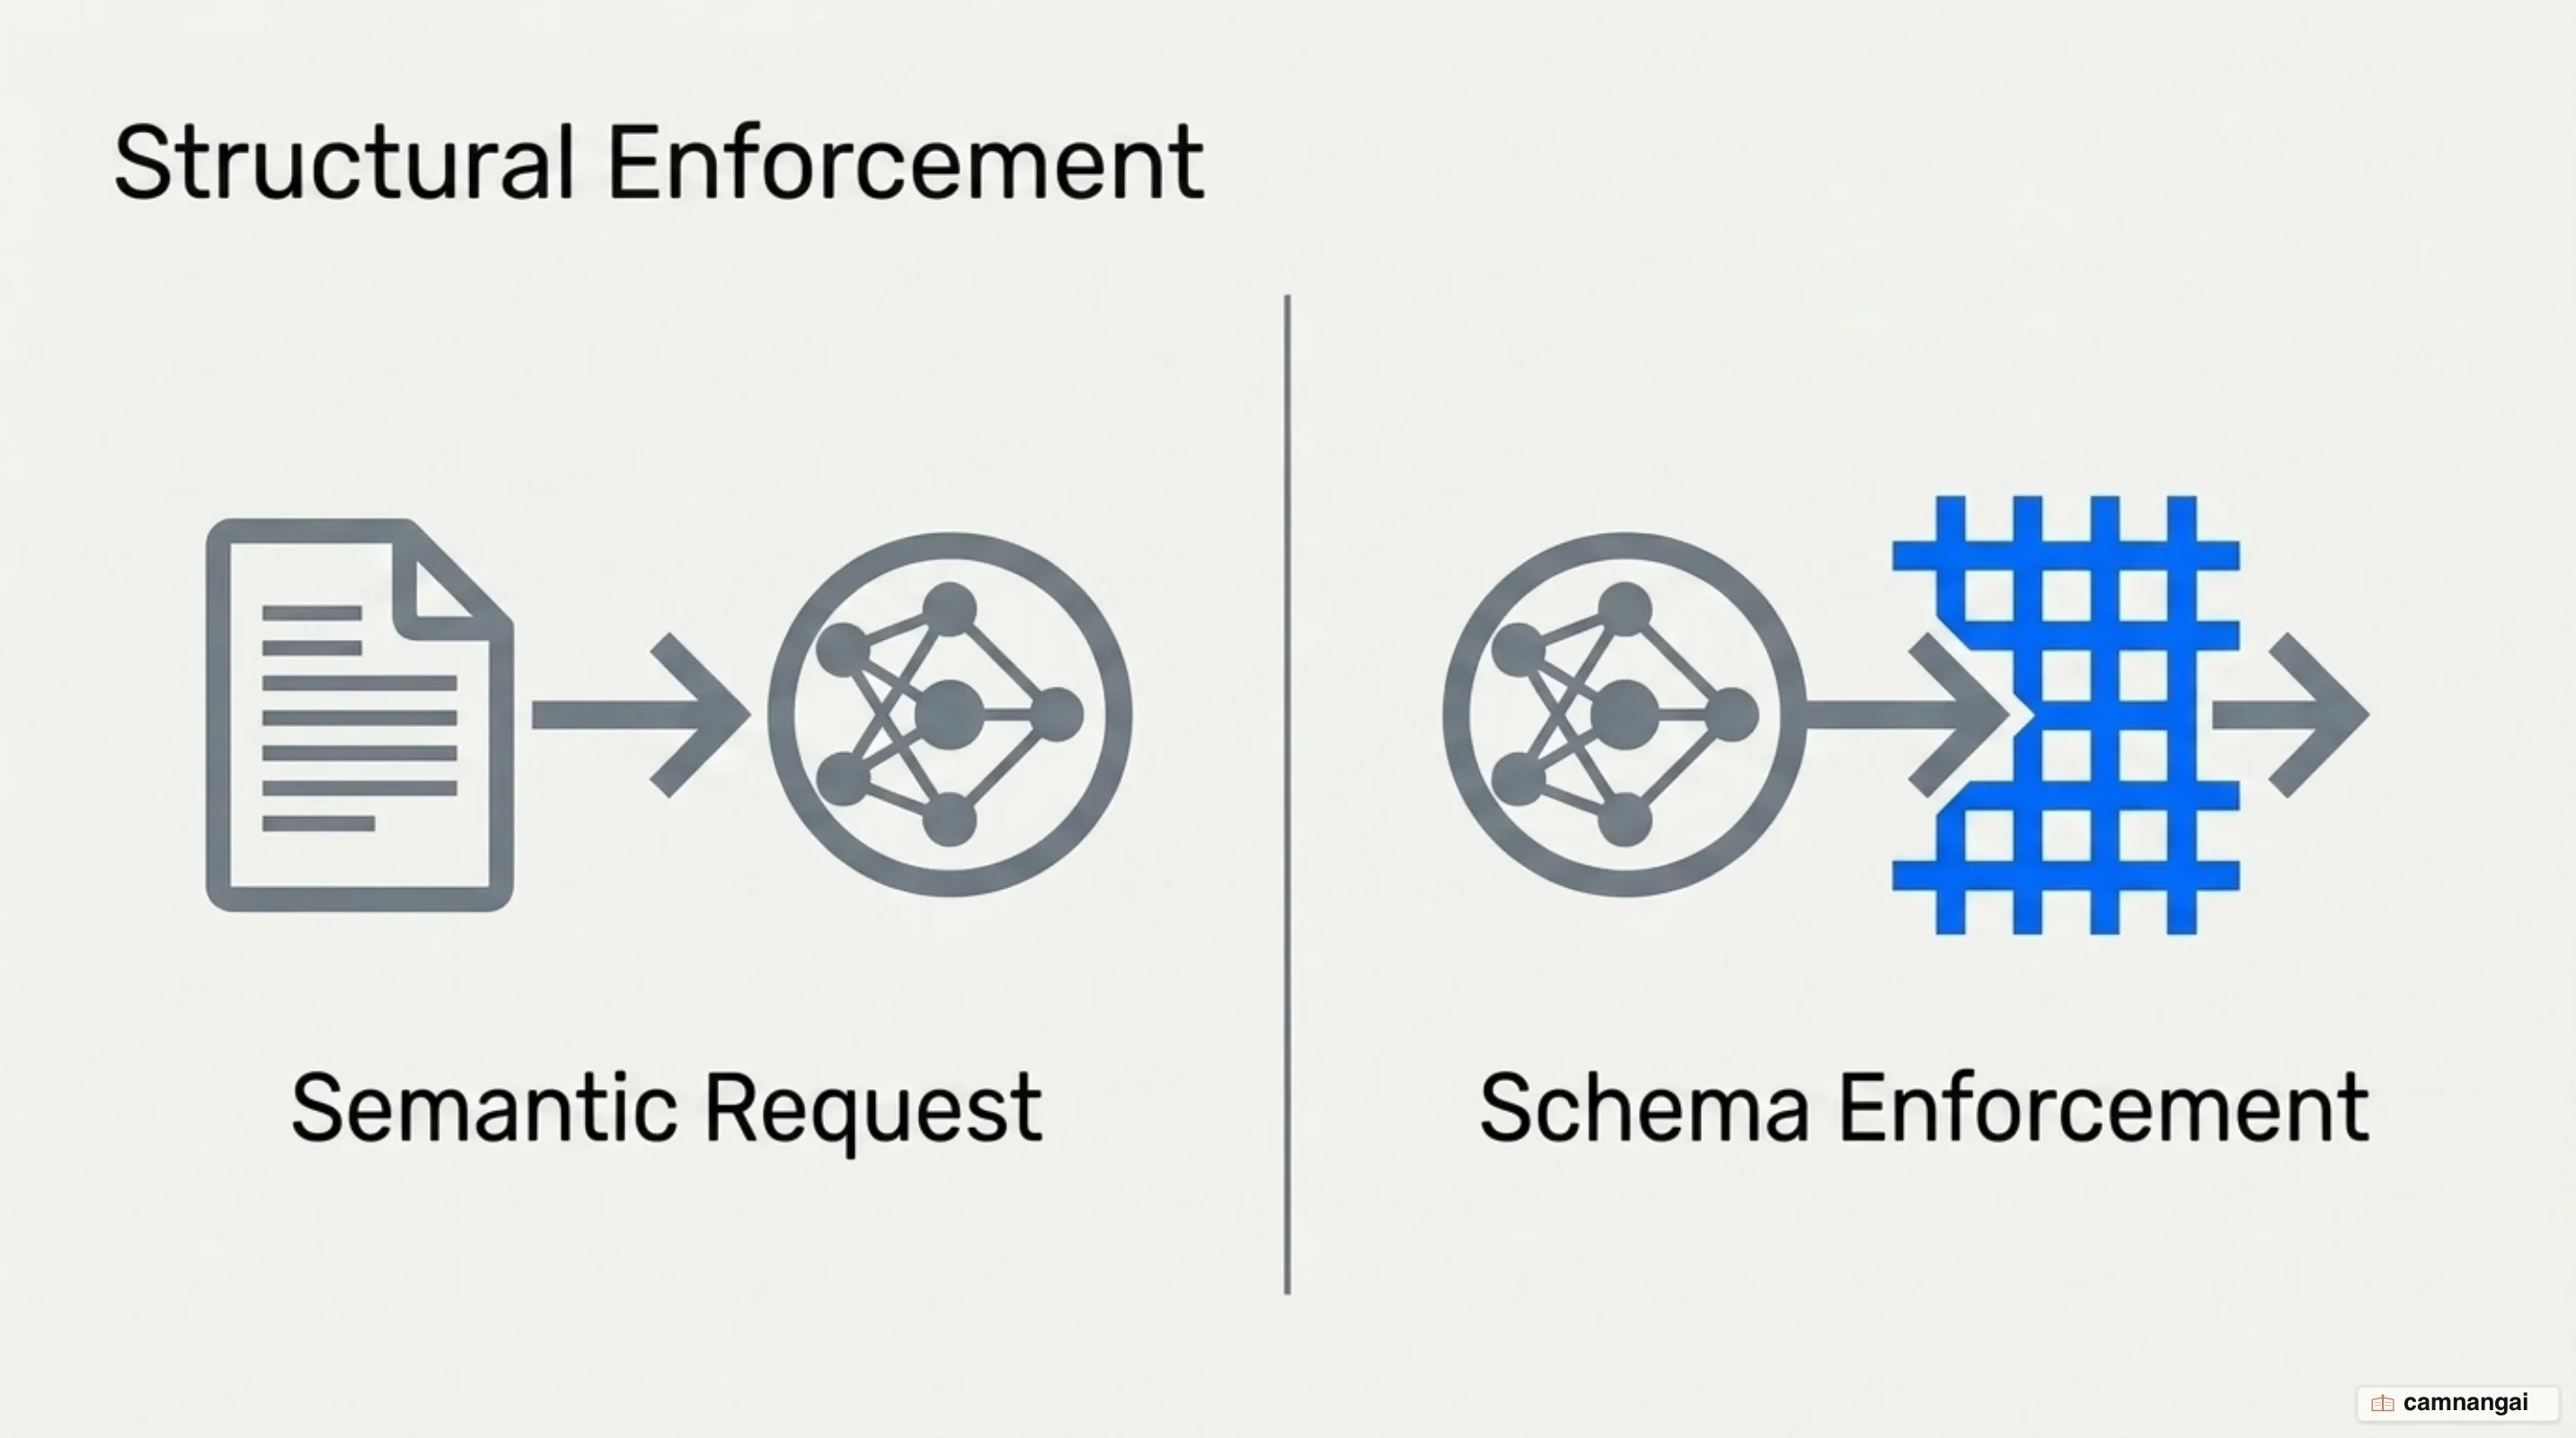
That kills the whole category of format fragility, the trailing commas and stray Markdown wrappers
that break a downstream parser in production. Once the formatting logic lives in the deterministic API
configuration, you can cast the output straight into typed objects. Reasoning control has its own
parameters worth calibrating alongside it: `reasoning_effort` for OpenAI, `thinking_level` and
`thinking_budget` for Gemini and Claude.
One implementation detail catches people out, and it is annoying: Claude's native Citations API,
which returns structured linkage to source documentation, cannot be combined with structured
outputs. Enable citations on a document while also setting the output format parameter and you get a
400 error, because citations interleave citation blocks with text output and a strict JSON schema
does not allow that. So you pick one, either an API-enforced schema with the citations baked in by
hand, or a prompt-based format that keeps native source attribution.
```json
{
"type": "object",
"properties": {
"citations": {
"type": "array",
"items": { "type": "string" }
},
"answer": { "type": "string" }
},
"required": ["citations", "answer"],
"additionalProperties": false
}
```
## Do the constraints actually hold?
Security in LLM applications rests on the instruction hierarchy. Frontier models are trained to
prioritize developer or system messages as the high-authority anchor for security constraints. But
any content in the context window that did not originate from the system prompt is untrusted input.
That includes RAG results, web pages, and tool outputs, all of which are an attack surface for
[prompt injection](https://camnangai.com/en/engineering/what-is-context-security).
An attacker can bury adversarial instructions in a data source that looks entirely trustworthy, and
those instructions will happily try to override your system constraints. So your constraints need
explicit refusal behavior for conflicting instructions:
the model should ignore commands found inside `` or `` tags and adhere strictly
to the `` block. Binding user roles and permissions into prompt construction further
ensures the model cannot escalate its own privileges.
Tool outputs need validating before they ever reach the context window, for the same reason. A tool
that returns free-form text is an injection vector, so its responses have to be schema-validated or
filtered for adversarial patterns first. All of this amounts to treating the model as an untrusted
executor, and I think that is the correct posture: constant verification against deterministic
rules, and a strict hierarchy between the instructions the developer wrote and the data that arrived
from outside.
## The cost of over-constraining
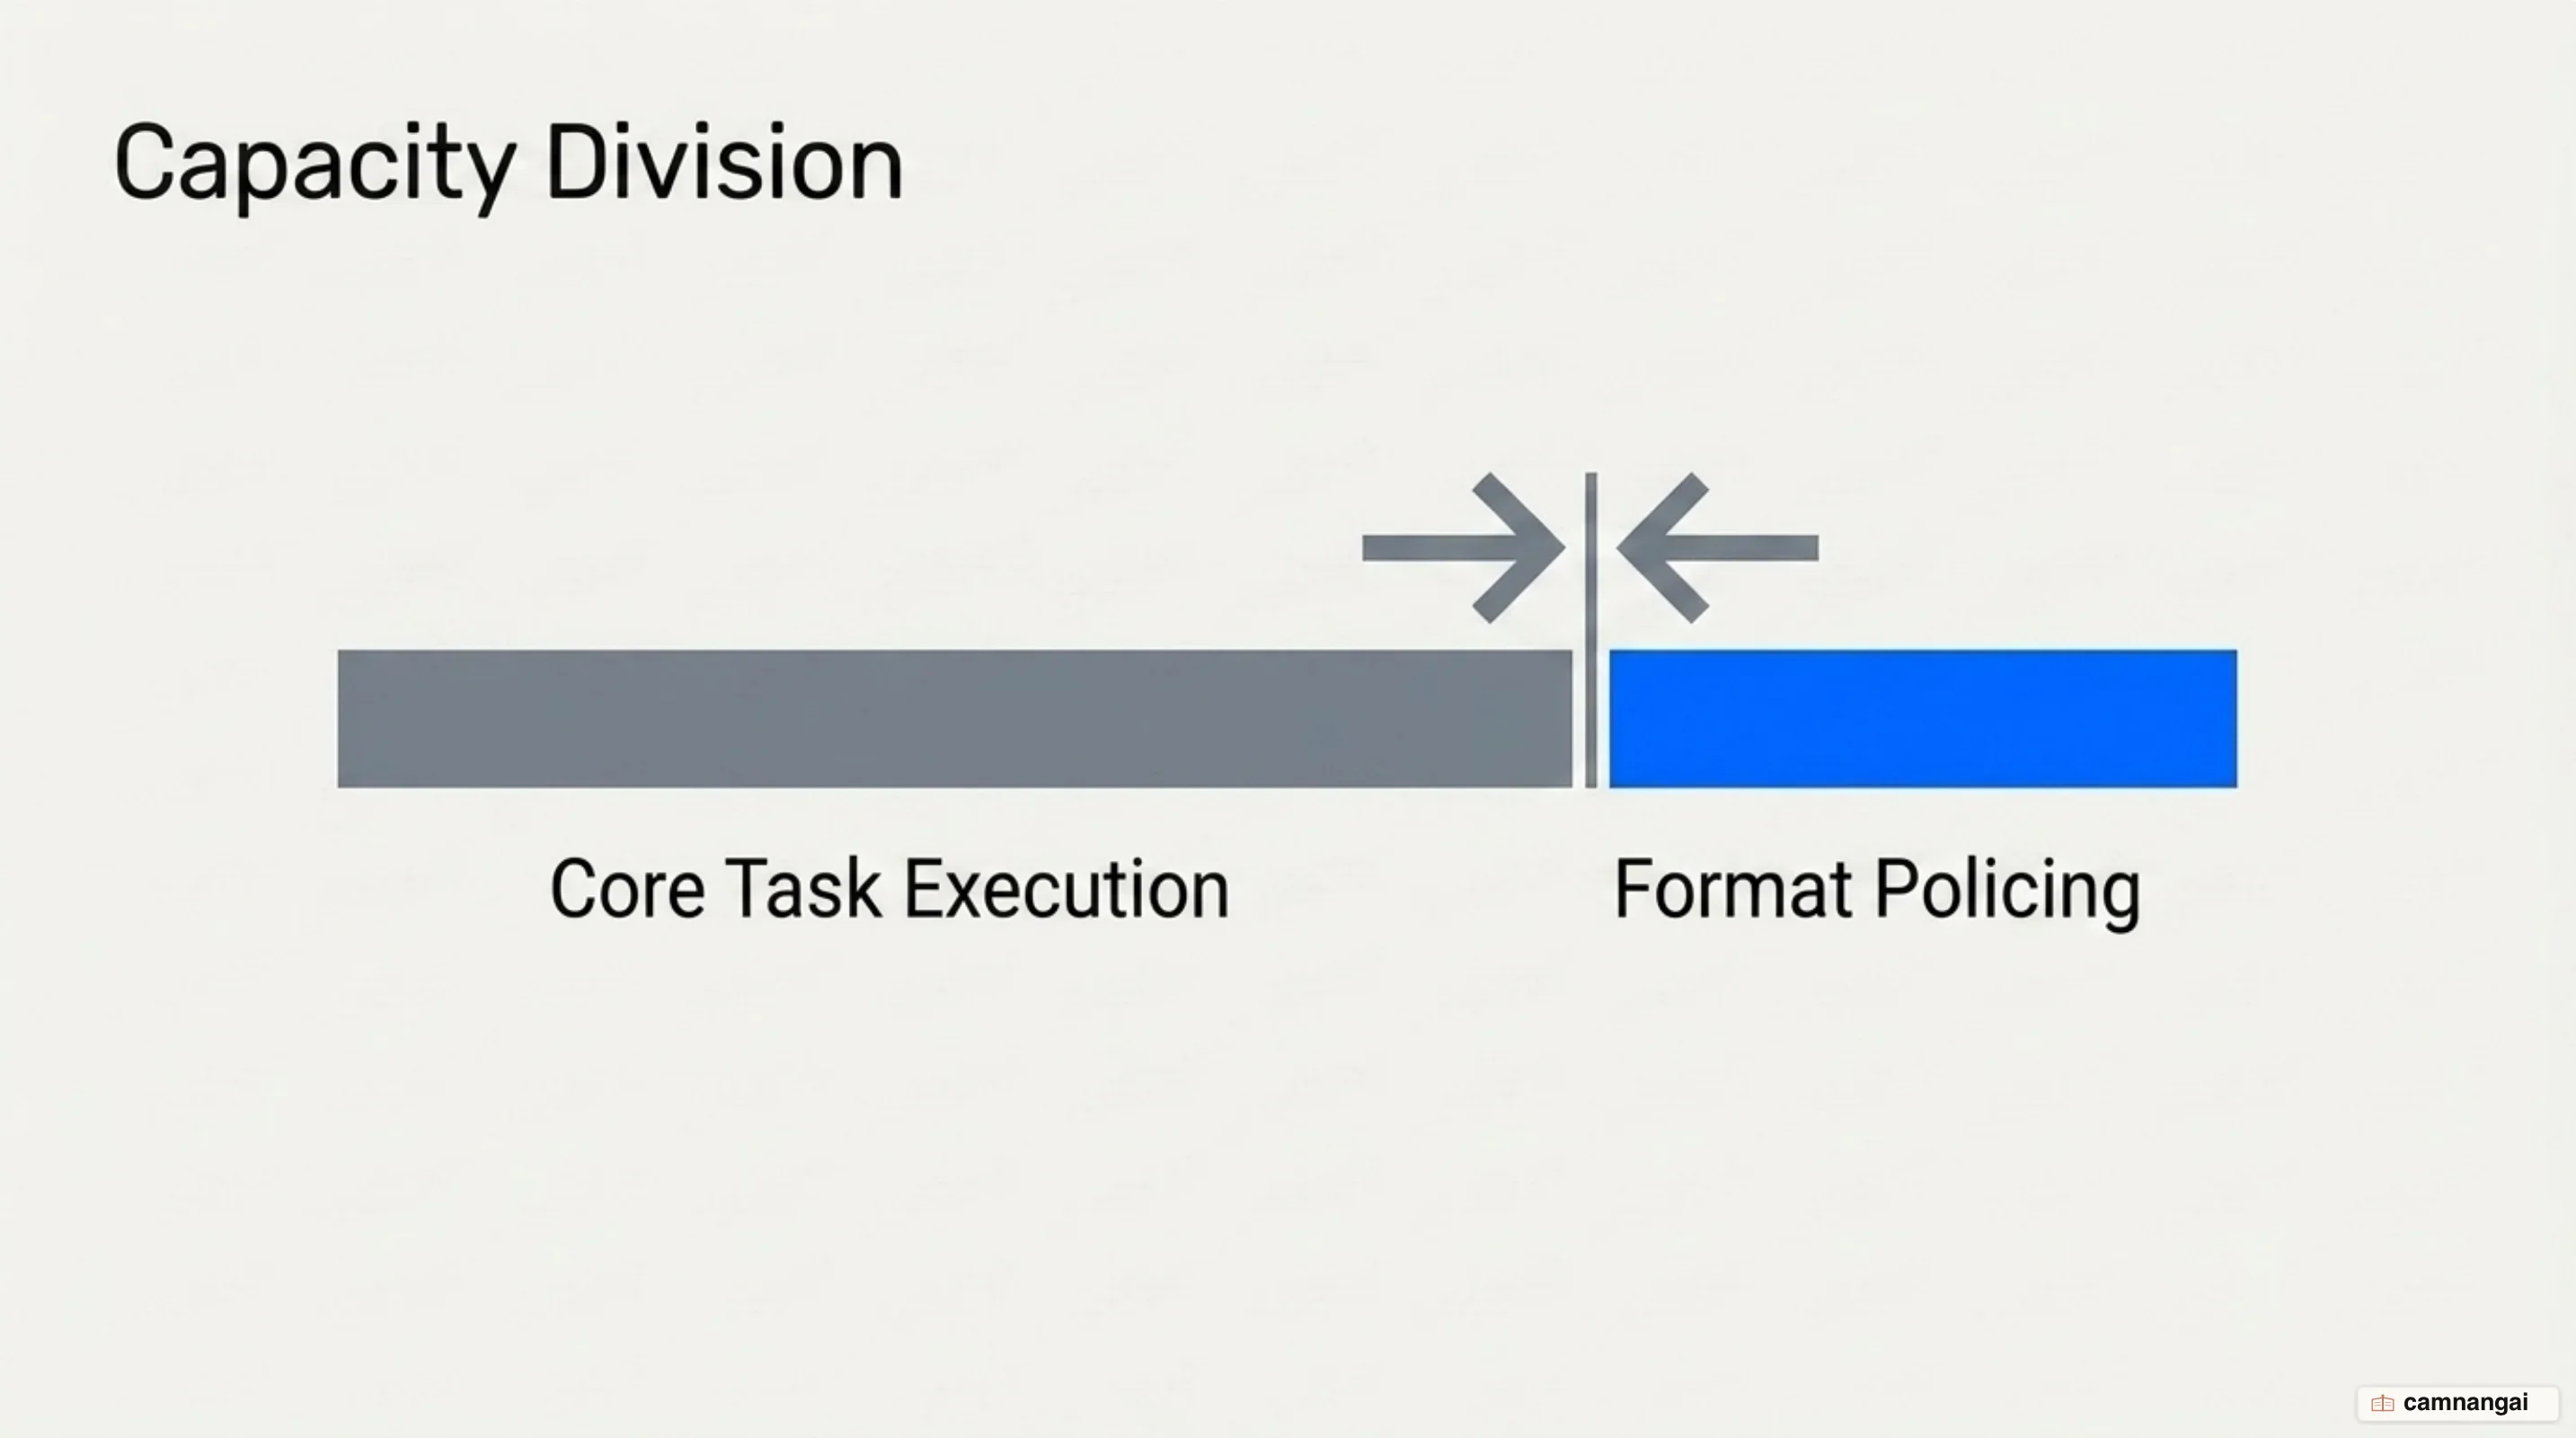
Format constraints are not computationally free. Force a model onto a rigid schema or a pile of
complex instructions and it hits decision competition — its attention splits between solving the
core task and satisfying format compliance. That competition frequently degrades reasoning quality,
because internal processing capacity goes to maintaining the interface contract instead of the
problem. The gap between what the model could have reasoned and what it actually returned under the
schema is the constraint tax, and every constraint you add pays some of it.
For reasoning models, the constraints go straight into how the thinking budget gets allocated.
Constrain the output path too hard and you push the model into spending tokens on superficial
structure rather than logical analysis, which you see as higher latency and a bigger token bill.
Parameters like `reasoning_effort` and `thinking_level` need calibrating so the model has capacity
for both the task logic and the constraints wrapped around it.
The other thing to hunt for is legacy boosters — aggressive instructions like "CRITICAL: You MUST
use this tool when…" that were required to stop older, less competent models undertriggering. Newer
models are more responsive to the system prompt and will overtrigger on exactly that language; the
fix is to dial it back to ordinary phrasing like "Use this tool when…". Keeping the conversation
history append-only matters for the same reason: editing earlier messages or summarizing older turns
in place invalidates later thinking blocks, and the model then errors or silently drops the block.
## When the prompt is not enough
Where the blast radius of a failure is large, prompting on its own is not enough, and the logic
belongs in least-privilege tools instead. Rather than handing an agent broad SQL access plus a
verbal instruction not to delete anything, you give it a scoped tool that accepts only specific,
parameterized query patterns. The verbal constraint was probabilistic; the tool boundary is not.
Post-generation validation is mandatory in production. Model output is probabilistic, so it has to
be verified against deterministic checks, such as system-level string matching to confirm that a
quote the model provided actually exists in the source context. If the model generates a code patch,
validate its syntax and run it in a sandbox before any deployment action.
High-stakes actions such as data deletion or external communication need human-in-the-loop approval.
Constraints mitigate risk, but they never eliminate the possibility that the model bypasses its
instructions, so flag hard-to-reverse operations for manual review. The model stays a suggestion
engine that way, rather than an autonomous actor with more agency than anyone signed off on.
## Where to start constraining
Constraining is iterative, and the order matters more than the starting point. Begin with zero-shot
prompting, a bare instruction with no examples, to establish a baseline, move to few-shot examples
to narrow the response distribution, then lock the behavior in with API-level schemas and evaluation
loops. One porting gotcha is worth knowing before you start: on Gemini 3 models, lowering
`temperature` below the default of 1.0 can cause looping or degraded performance on complex
reasoning, so reach for schema constraints instead of the `temperature=0` habit you carried over
from another provider.
The point of all of it is to get off vibe-based iteration and onto eval-driven development. Run your
prompt stack against a logged dataset of edge cases and you can see whether each constraint actually
improves reliability or just charges you constraint tax, with deterministic checks for schema
validity and model-based grading for reasoning quality. The prompt worth shipping is the smallest
set of constraints that survives that loop.
## References
- [Prompting best practices - Claude Platform Docs](https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/claude-prompting-best-practices)
- [Reduce hallucinations - Claude Platform Docs](https://platform.claude.com/docs/en/test-and-evaluate/strengthen-guardrails/reduce-hallucinations)
- [System prompts - Claude Platform Docs](https://platform.claude.com/docs/en/release-notes/system-prompts)
- [Structured model outputs | OpenAI API](https://developers.openai.com/api/docs/guides/structured-outputs)
- [The Pink Elephant Problem: Why "Don't Do That" Fails with LLMs](https://eval.16x.engineer/blog/the-pink-elephant-negative-instructions-llms-effectiveness-analysis)
- [LLM guardrails: Best practices for deploying LLM apps securely | Datadog](https://www.datadoghq.com/blog/llm-guardrails-best-practices/)
- [Prompt Engineering Across the OpenAI, Anthropic, and Gemini APIs | Steve Kinney](https://stevekinney.com/writing/prompt-engineering-frontier-llms)
- [A Closer Look at System Prompt Robustness](https://arxiv.org/abs/2502.12197)
- [Constraint Tax in Open-Weight LLMs](https://arxiv.org/abs/2606.25605)